Shop/LLM Evals Kit
SDET · 3–6 yrs
LLM Evals Kit
Test LLM features like any other feature: a dataset, graders, an LLM judge and a CI gate.
- By QA Bash
- 3–6 yrs experience
- Code · PDF
- Updated October 2026
- English
What you'll be able to do
- Build a dataset that measures an LLM feature honestly
- Choose code graders or an LLM judge for each check
- Calibrate a judge before you trust its scores
- Block prompt or model changes that break cases in CI
Kit contents
9 sections · Python repo (zip) + PDF guide
RepositoryPython · Anthropic SDK
- Feature under test: a bug triager
- Dataset with hard-case tags
- 6 code graders
- LLM judge with strict format
- Offline fake model
- SDK tests with a mocked network
- GitHub Actions gate
Look inside
Real pages from the download. Click to enlarge.
Free sample · from Part 4
Parse failures are failures
If the model returns text with no JSON, the runner records the case as failed with the error. It doesn't crash the run, and it doesn't skip the case. A skipped case would push your pass rate up for the wrong reason.
Requirements
- Python 3.10 or newer
- An Anthropic API key for real runs (offline mode is free)
- Comfortable reading Python
Description
A Python eval setup built on the Anthropic SDK for a bug triage feature, with a tagged dataset, code graders, a calibrated judge, run comparison and CI. 32 tests pass offline.
- 24-case tagged dataset
- 6 code graders and an LLM judge
- Run comparison for prompt and model changes
- GitHub Actions gate
- 13-page guide
Who this kit is for
- SDETs asked to test an AI feature
- QA leads who need a release gate for LLM changes
- Engineers moving into AI quality work
Who it's not for
- Testers with no Python: start with AI for QA Engineers
Frequently asked questions
How do I get the files?
Instantly. After payment the Download button appears on the product page and in Dashboard → Purchases. You can download again any time while your account is active.
What payment methods can I use?
UPI, debit and credit cards, net banking and wallets — processed securely by Razorpay. QA Bash never sees your card or bank details.
Is it a subscription?
No. You pay once and keep it.
Can I get a refund?
Digital files can't be returned once downloaded, so sales are final after download. If you haven't downloaded within 7 days, or a file is broken and we can't fix it, you get a full refund. See the refund policy for details. Refund policy →
Can I use it at work?
Yes — for your own learning and in your own or your employer's projects. Please don't share or resell the files.
Is everything else on QA Bash still free?
Yes. Learning paths, tools, Testathon, certificates and the community stay free. The shop is optional.
More kits from QA Bash
 26 passing tests
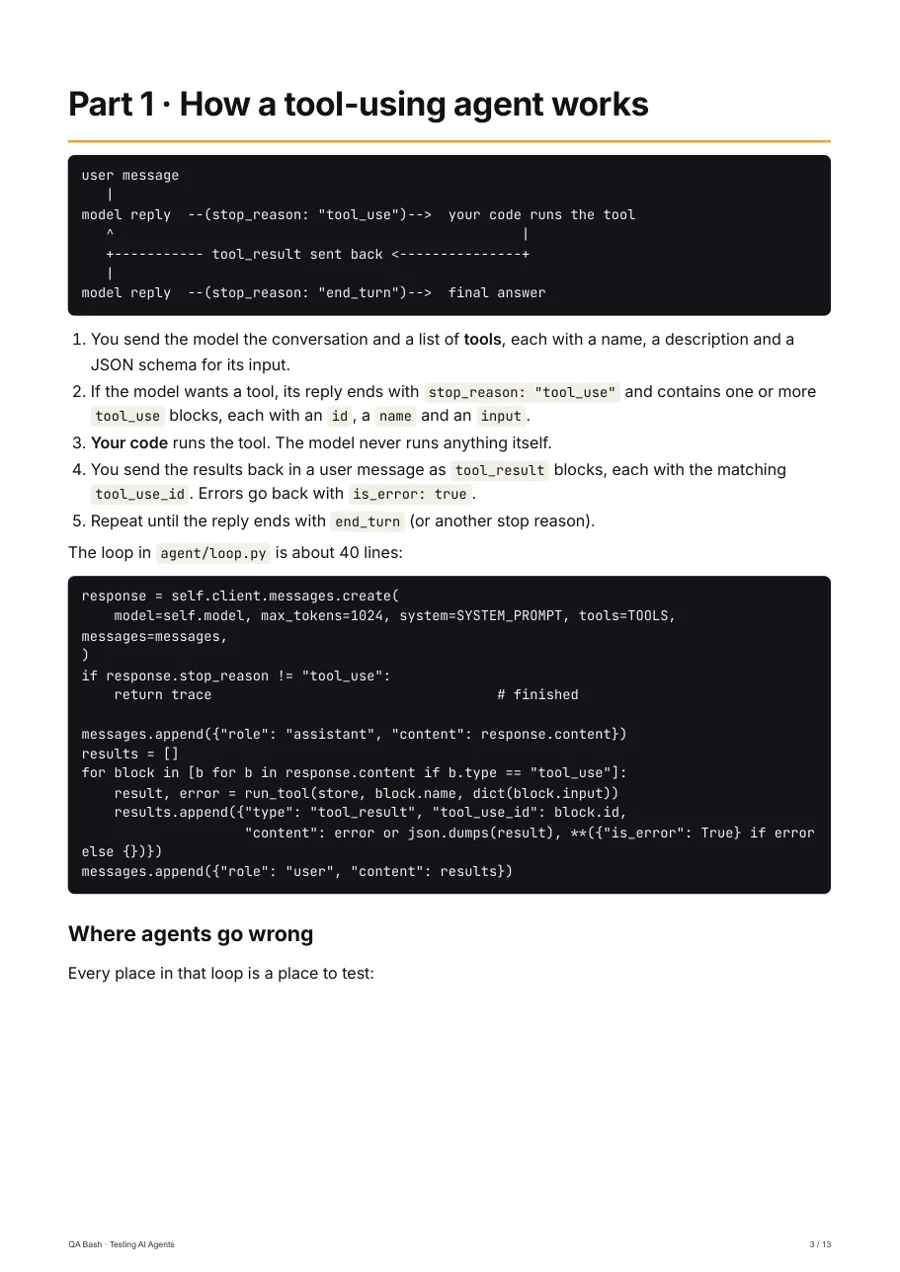
Testing AI Agents
QA Bash
Test what an AI agent does: tool calls, side effects, guardrails, prompt injection and loop limits.
₹799₹99920% off
 300 interview Q&A
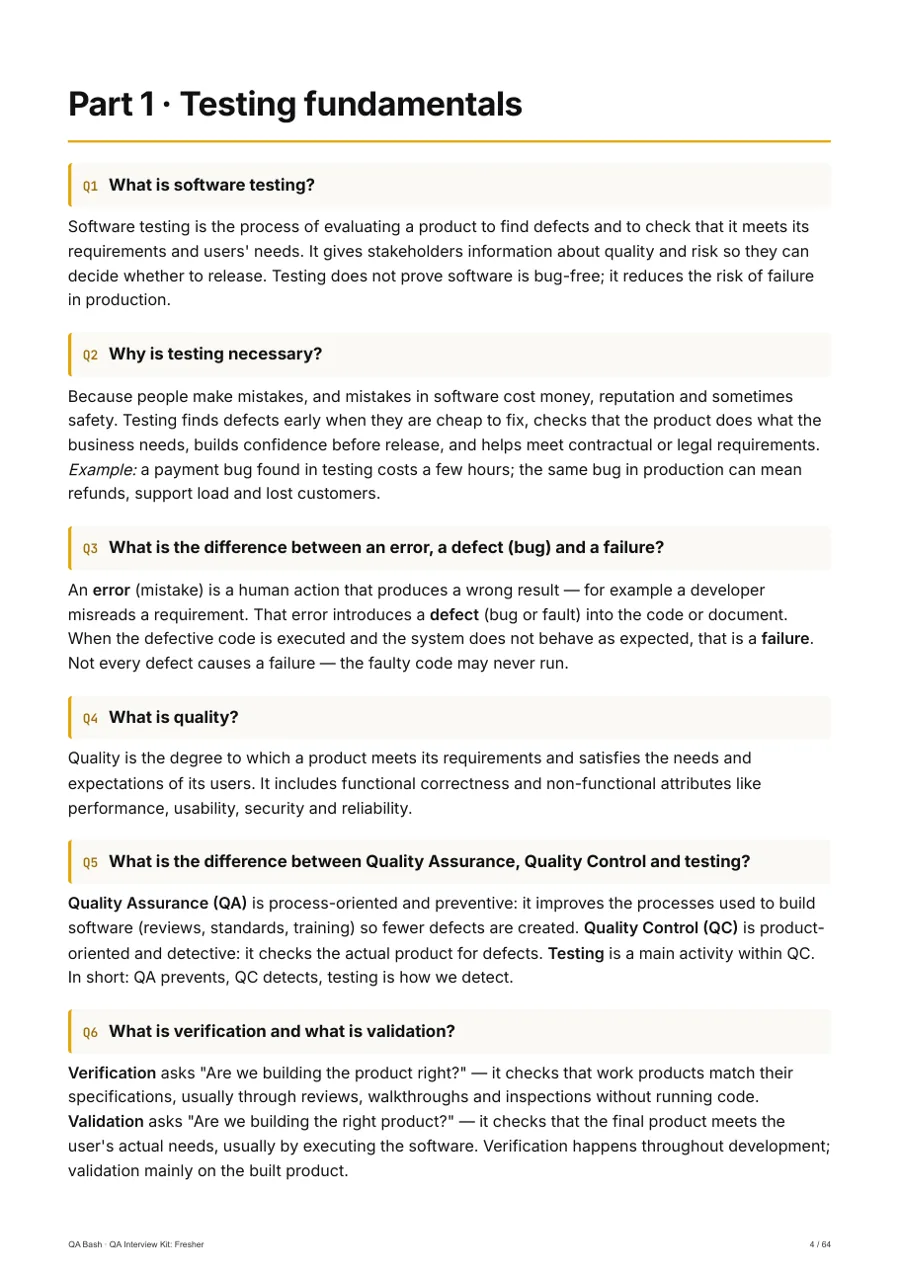
QA Interview Kit: Fresher
QA Bash
Walk into your first QA interview prepared, not guessing.
₹299₹37420% off
 5 ATS-ready templates
QA Resume & LinkedIn Kit
QA Bash
ATS-ready resumes that make recruiters stop scrolling.
₹199₹24920% off